AI moves fast.Understand what matters.
A curated perspective on AI: what matters, why it matters, and what comes next.
A sharper perspective for a brighter tomorrow.
Latest
View all
xAI’s Grok 4.6 reaches Amazon Bedrock with two deployment paths
Developers gain a 500K-token model with Converse and cross-Region inference, but API features, residency options and pricing differ…
Benchling details layered AWS defenses for multi-tenant AI code execution
The production design isolates AgentCore sessions, restricts DNS and S3 access, and continuously tests the controls, but its…
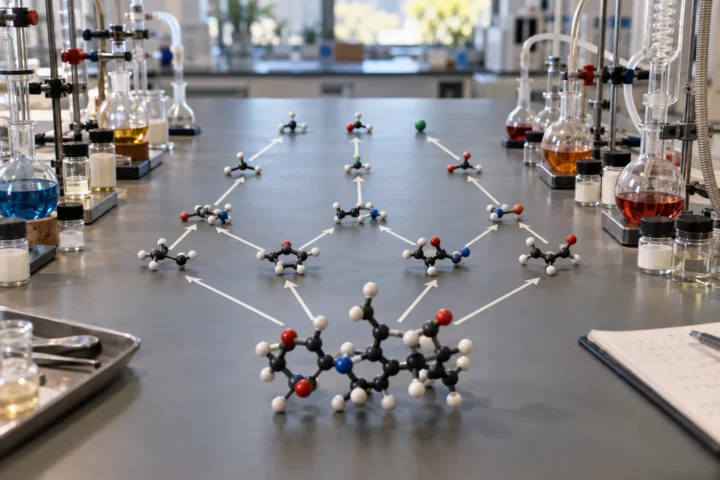
Microsoft open-sources RetroChimera for chemist-aligned synthesis planning
Expert reviewers accepted its routes for nine of ten challenging targets, though faster laboratory synthesis remains a projected…
TensorRT Edge-LLM Cuts Jetson Agentic Benchmark Run to 24 Minutes
NVIDIA attributes the 6.4x completion-time advantage over the published llama.cpp reference to NVFP4 quantization, cache reuse and tree-based…
NVIDIA Dynamo-Triton Adds Multi-GPU TensorRT Serving Through One Model Endpoint
NVIDIA’s eight-GPU Cosmos 3 Nano test cut mean generation latency from 156.595 seconds to 34.183 seconds, but it measured neither throughput nor deployment economics.
Read the story
Today’s top stories
View all
AWS publishes 38 open-source skills for more reliable healthcare AI agents
A 410-prompt evaluation found skill-equipped agents beat otherwise comparable baselines in 69.5% to 85.9% of comparisons, although results…
AWS documents six Amazon Bedrock prompt-caching patterns for lower inference costs
Cached input can cost up to 90% less on a hit, but write premiums, minimum token thresholds and…
Amazon Bedrock AgentCore adds managed OAuth consent portal for AI agents
The portal replaces customer-hosted session binding for AgentCore Gateway, while keeping each user’s provider grants separate and auditable…
Nemotron Post-Training Pipeline Reaches IMO 2026 Gold Threshold
The authors report a 30-of-42 score from a natural-language proof system and are releasing specialist checkpoints, code, data…
AI in practice
OpenAI launches ChatGPT for Teens with learning tools, default safeguards and parental controls
The new experience places users identified as ages 13 to 17 into a teen-focused version of ChatGPT that combines guided study features with age-appropriate protections, healthy-use prompts and…
Read the story
GitHub Copilot code review adds automatic comment resolution and multi-agent Lite reviews
The update reduces review-thread cleanup while GitHub-reported experiments link the Lite agent ensemble to…
AWS benchmark reframes OpenAI model costs around successful outcomes
The published results favor GPT-5.6 Luna in several tested cost-per-success scenarios, but configuration differences,…
More worth knowing
AWS documents dual-layer monitoring for production multi-agent systems
The reference architecture combines sampled quality evaluation with infrastructure investigation, while requiring separate inline safeguards for responses that must be checked before…
02
Google ADK Python 2.9.0 adds model failover, LiveKit voice support and YAML workflows
The release broadens agent deployment options, but changed resume semantics and stricter file-access rules require migration checks.
03
Marengo Embed 3.0 brings managed multimodal search to Amazon Bedrock Knowledge Bases
AWS customers can search video, audio and images by meaning, while paying separately for storage, retrieval and Marengo embedding generation.